
Key Info
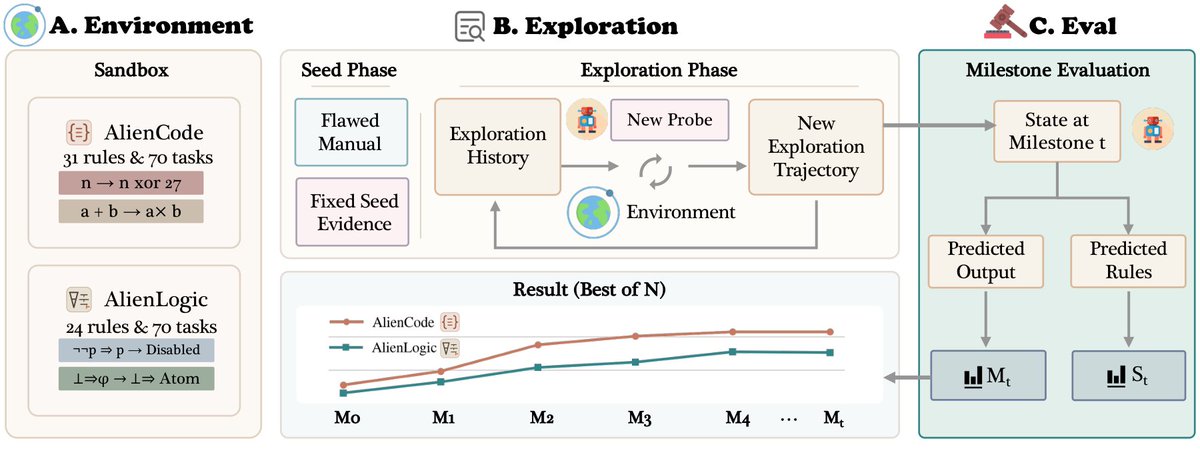
Researchers from Tencent Hy, Fudan University, and Tsinghua University released ExplorationBench, a benchmark for measuring how AI systems explore, using verifiable "Alien Worlds" sandboxes where rules are executable and conflict with familiar knowledge.
Highlights
- Benchmark targets scientific discovery skills: framing hypotheses, designing experiments, and learning from results
- Verifiable Alien Worlds have executable rules so every answer is checked exactly
- Rules deliberately conflict with familiar knowledge, so model recall alone cannot solve the tasks
- Two sandboxes included: AlienCode with 31 hidden rules (further details truncated in original post)