
Key Info
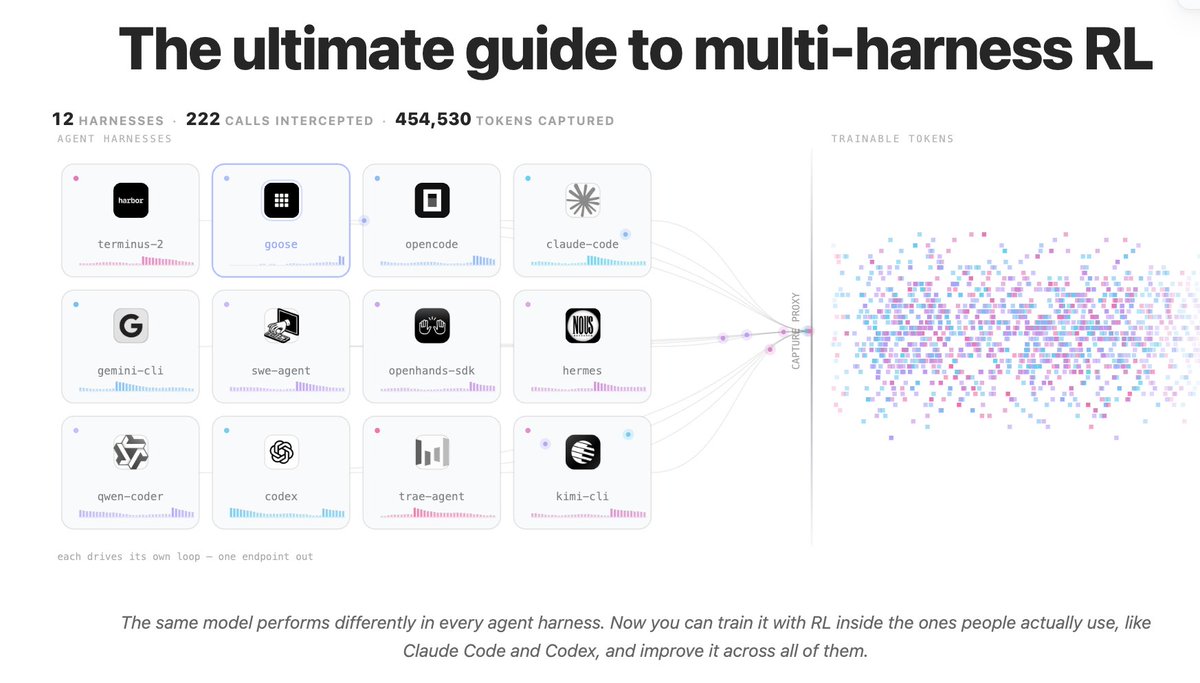
A Hugging Face team released an open, practical guide to multi-harness reinforcement learning, demonstrating that the same model with identical weights scores 62% in one agent harness versus 33% in another.
Highlights
- The core trick: instead of modifying the harness, point it at a proxy that speaks all four API formats coding agents use (OpenAI Chat Completions, OpenAI Responses, Anthropic Messages, Gemini)
- The proxy records the exact token ids and logprobs that vLLM sampled, which are then used for training
- No changes are needed to Claude Code, Codex, or OpenCode harness code
- Model LFM2.5-2.6B was trained across 4 harnesses simultaneously
- Everything is open-sourced