
Key Info
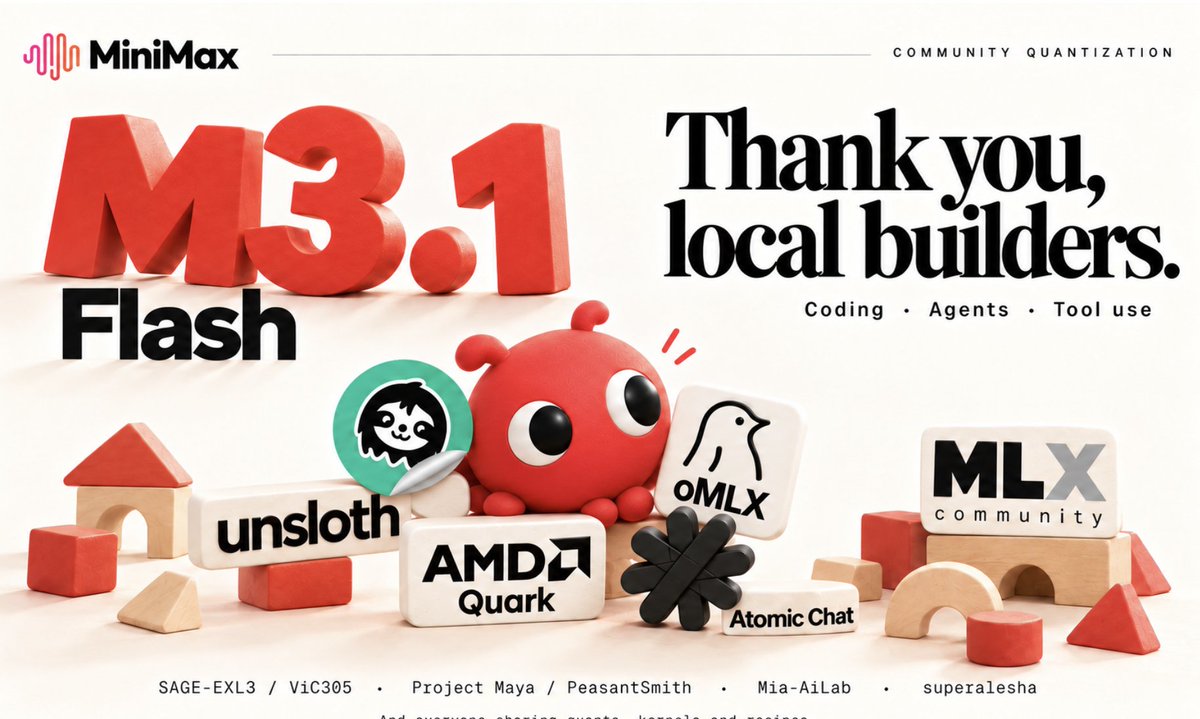
MiniMax highlighted community work that makes its 428B-parameter M3.1 Flash model easier to run locally through quantization, including a 2-bit Dynamic GGUF build at 143.9 GB.
Highlights
- Lower-bit weights cut the memory needed to load the model and the weight data moved during decoding.
- Unsloth (@UnslothAI, @danielhanchen) produced 2-bit Dynamic GGUF weights at 143.9 GB with calibration and fidelity testing across coding, tool use and other workloads.
- @ViC305 contributed SAGE-EXL3 with token-level fidelity measurements and a single-DGX-Spark recipe.
- @PeasantSmith contributed Project Maya quants and expert offloading.
- Useful savings require careful calibration, efficient low-bit kernels, and hardware-aware placement of experts across GPU and system RAM.