
Key Info
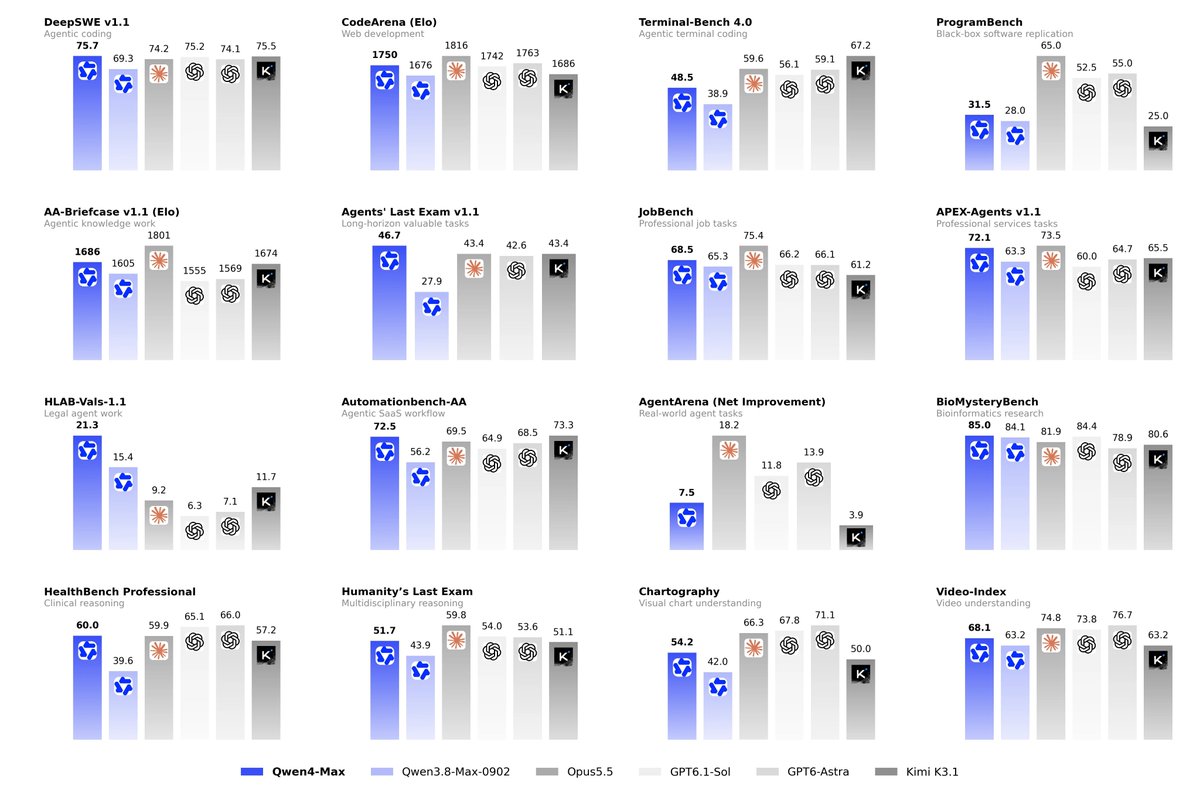
Qwen announced Qwen4-Max, a model built on a new MoE architecture with native vision and a 1M-token context window, positioned for work, creativity and discovery tasks.
Highlights
- Qwen says it outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over 60% in internal evaluation.
- Pricing is $1.5/M input tokens, $4.5/M output tokens, and $0.075/M tokens for implicit caching.
- The model is aimed at professional tools, long-horizon execution and higher-quality deliverables.
- Showcased use cases include 3D modeling, game development, manufacturing (sketch to industrial production), finance, law, healthcare, and autonomous design and synthesis of novel coolant materials for science.