Key Info
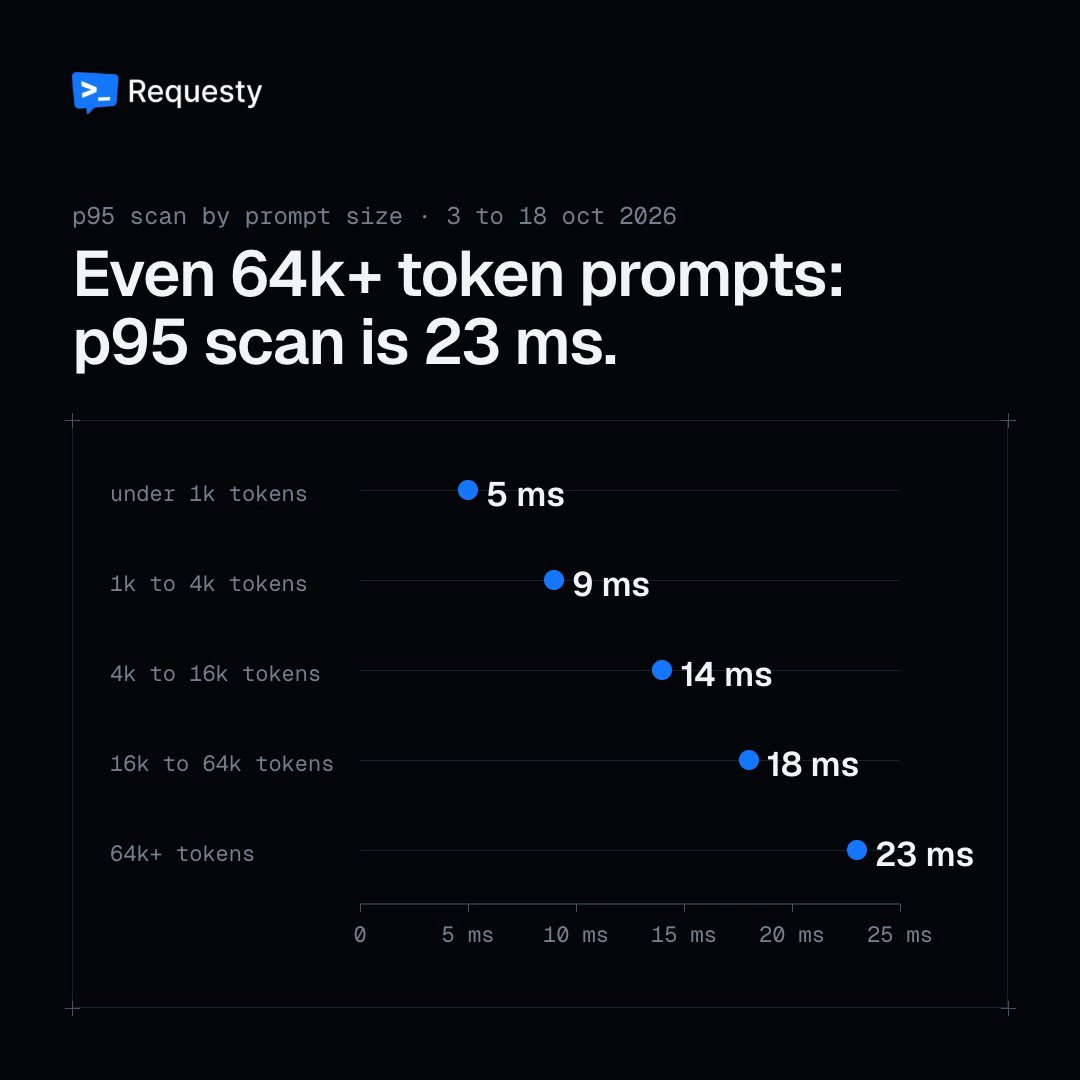
Requesty shared measured latency for its AI gateway guardrails over the period Oct 3–18, reporting a 4 ms median and 15 ms p95, with p95 rising to only 23 ms on prompts exceeding 64k tokens.
Highlights
- Median guardrail response time: 4 ms
- p95 latency: 15 ms
- p95 on 64k+ token prompts: 23 ms
- The figures are framed as an argument that slow guardrails add avoidable per-request latency in production