
Key Info
Requesty published its week 46 (Nov 9–15) gateway charts, highlighting how token usage is distributed across sessions and how much of the input load is served from prompt cache.
Highlights
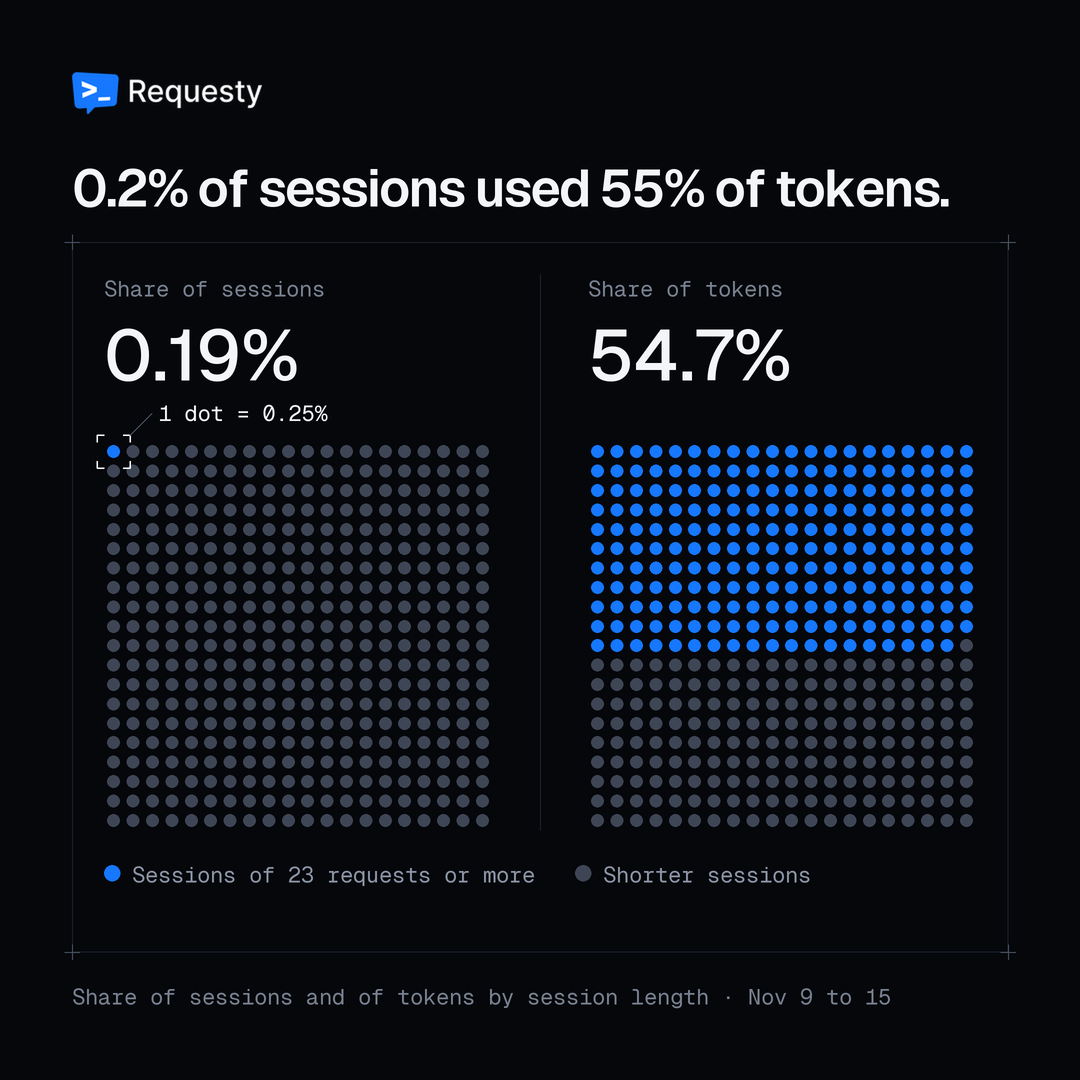
- 0.2% of sessions consumed 55% of all tokens, with long agent loops driving the bill.
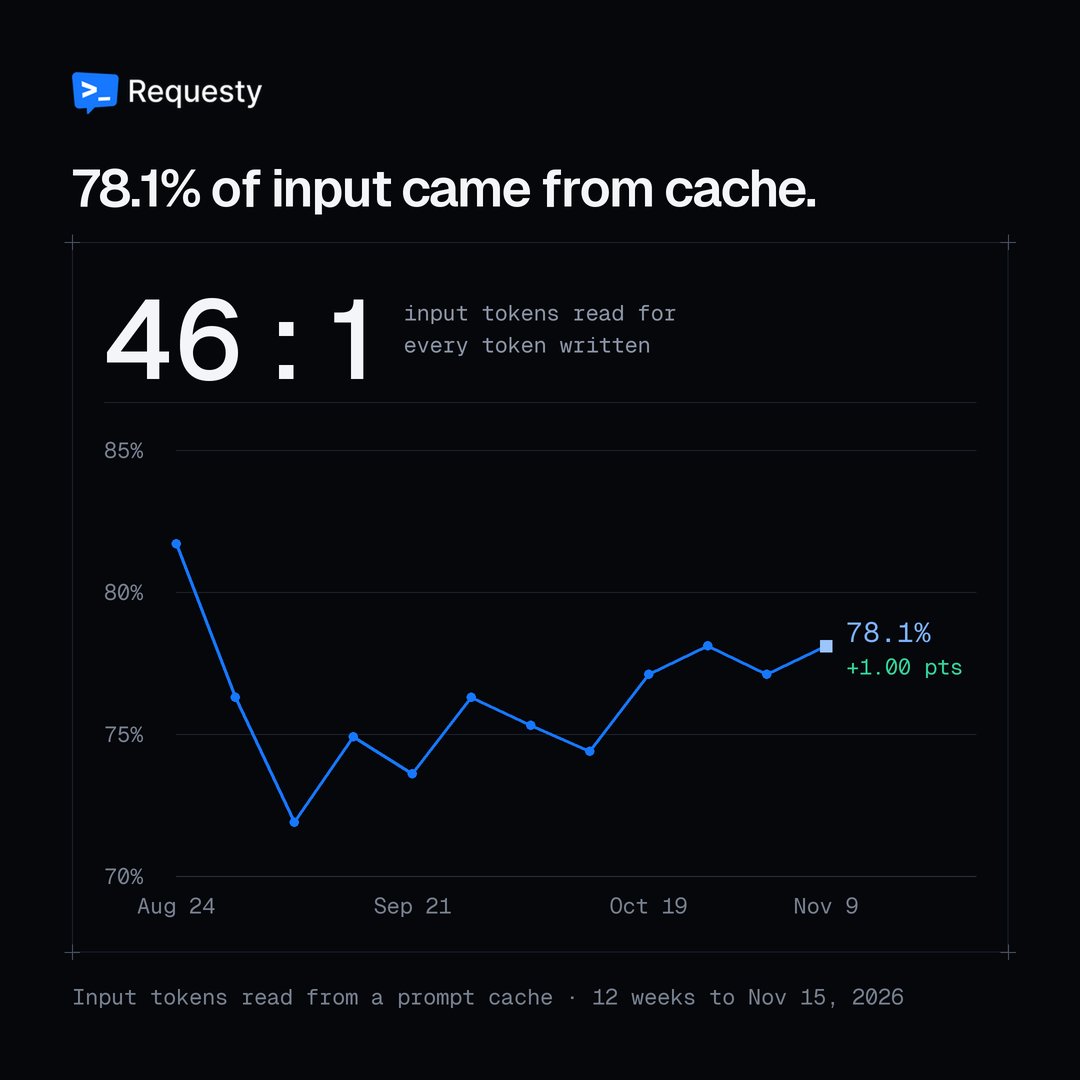
- 78.1% of input tokens were read from a prompt cache.
- Models read 46 input tokens for every token they wrote.
- The data comes from five charts covering who climbed and where tokens went on the Requesty gateway.