
Key Info
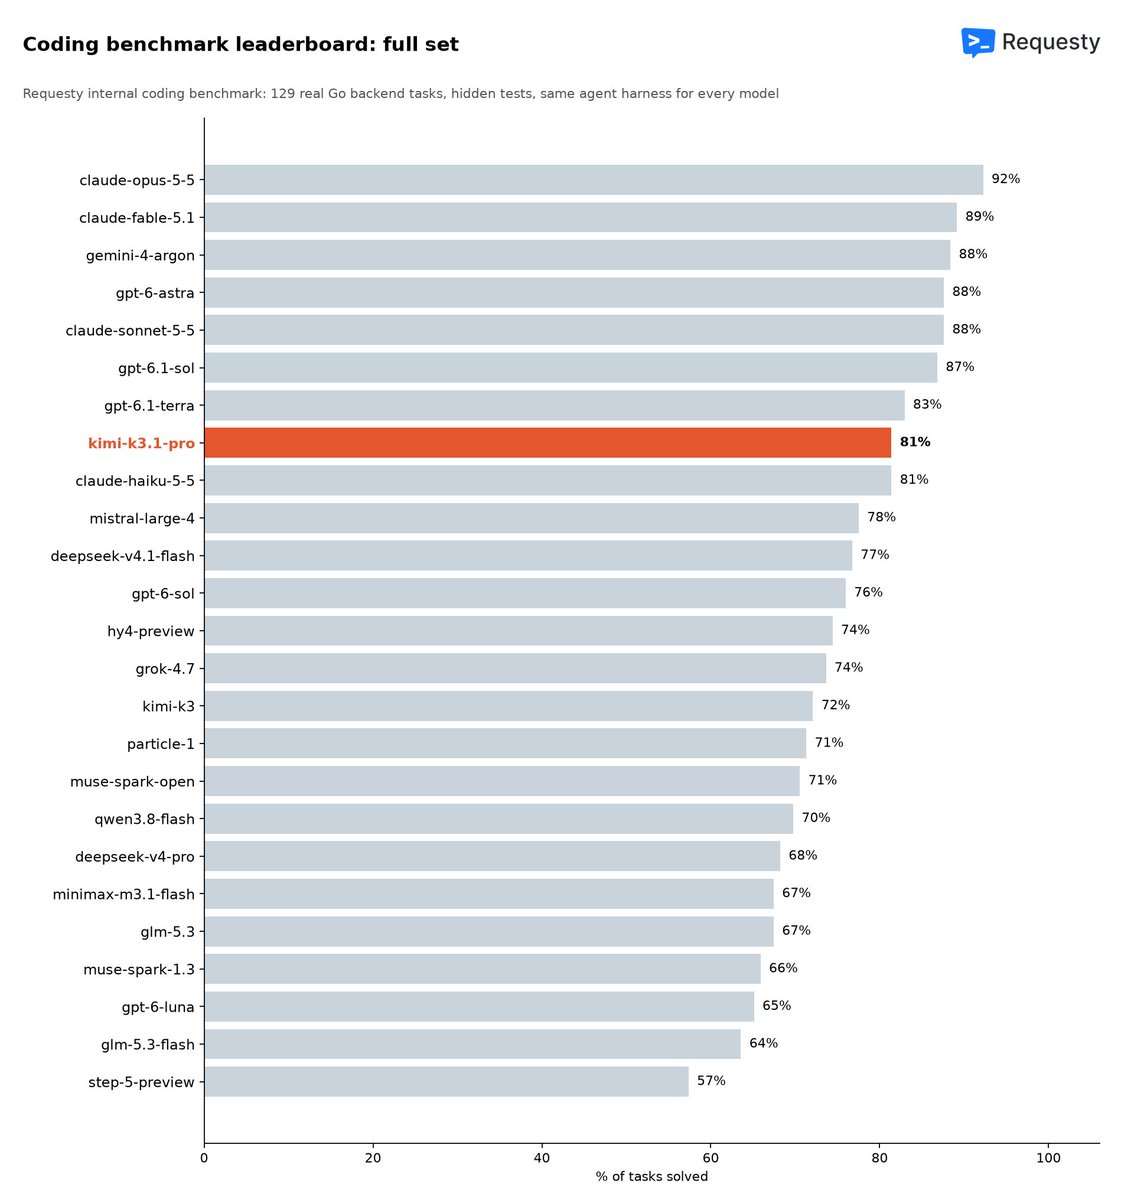
Requesty says Kimi K3.1 Pro solved 81% of its internal set of 129 Go backend tasks, placing it alongside frontier lab models, and argues against choosing models based on third-party benchmarks alone.
Highlights
- Requesty ran its own evaluation of Kimi K3.1 Pro on 129 Go backend tasks.
- The model solved 81% of those tasks, described as on par with frontier labs.
- The post pushes back on FrontierCode 2.0's claim that open models struggle.
- Recommendation: benchmark new models on your own workload rather than someone else's benchmark.