
Key Info
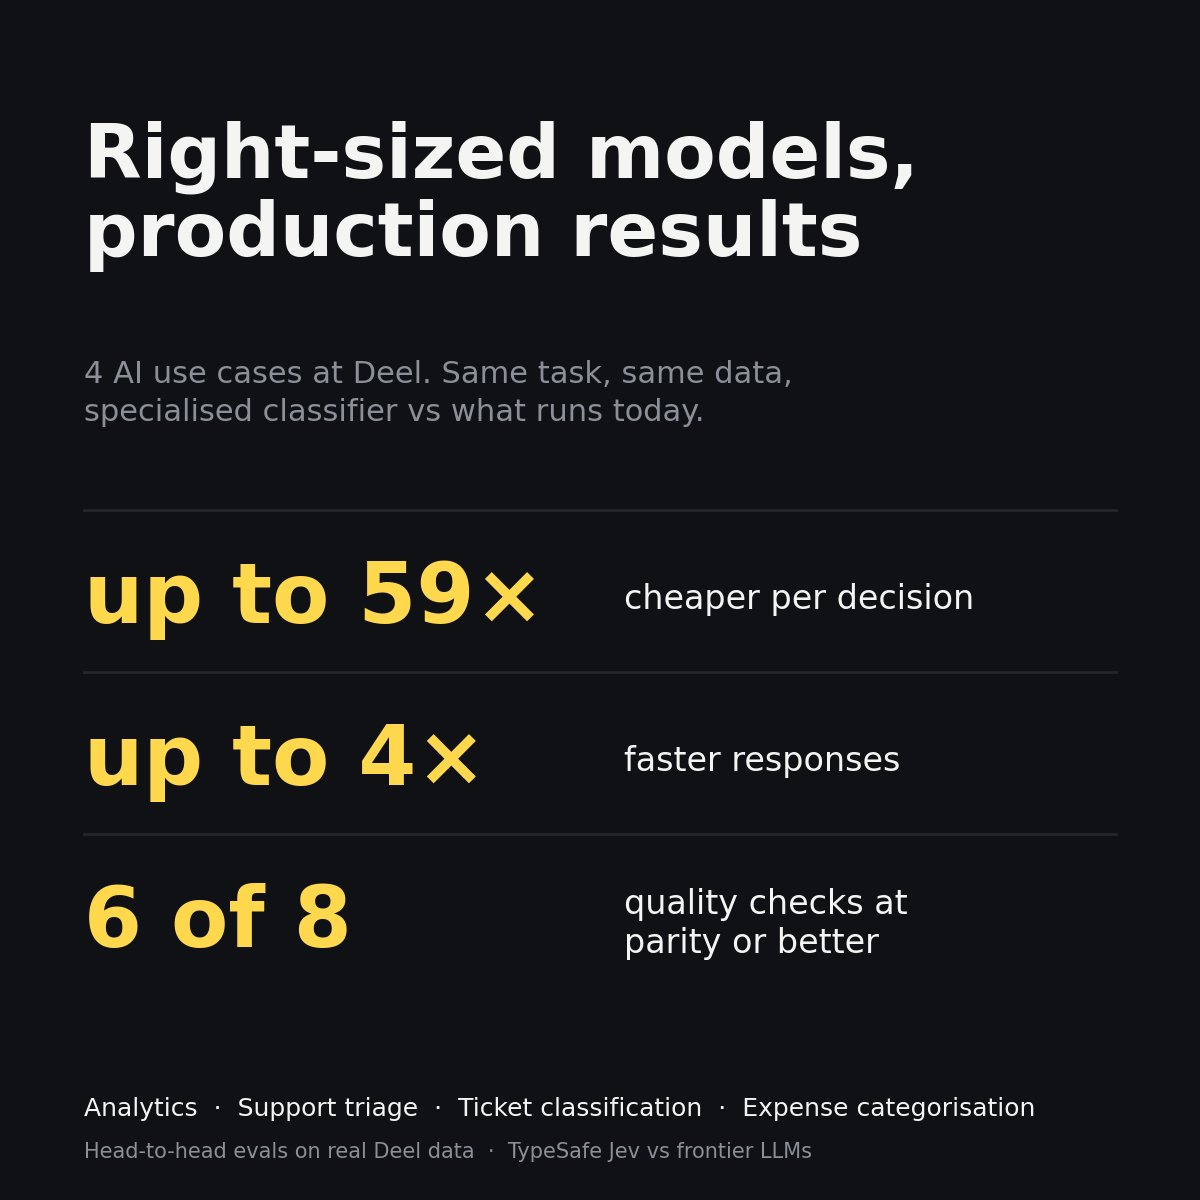
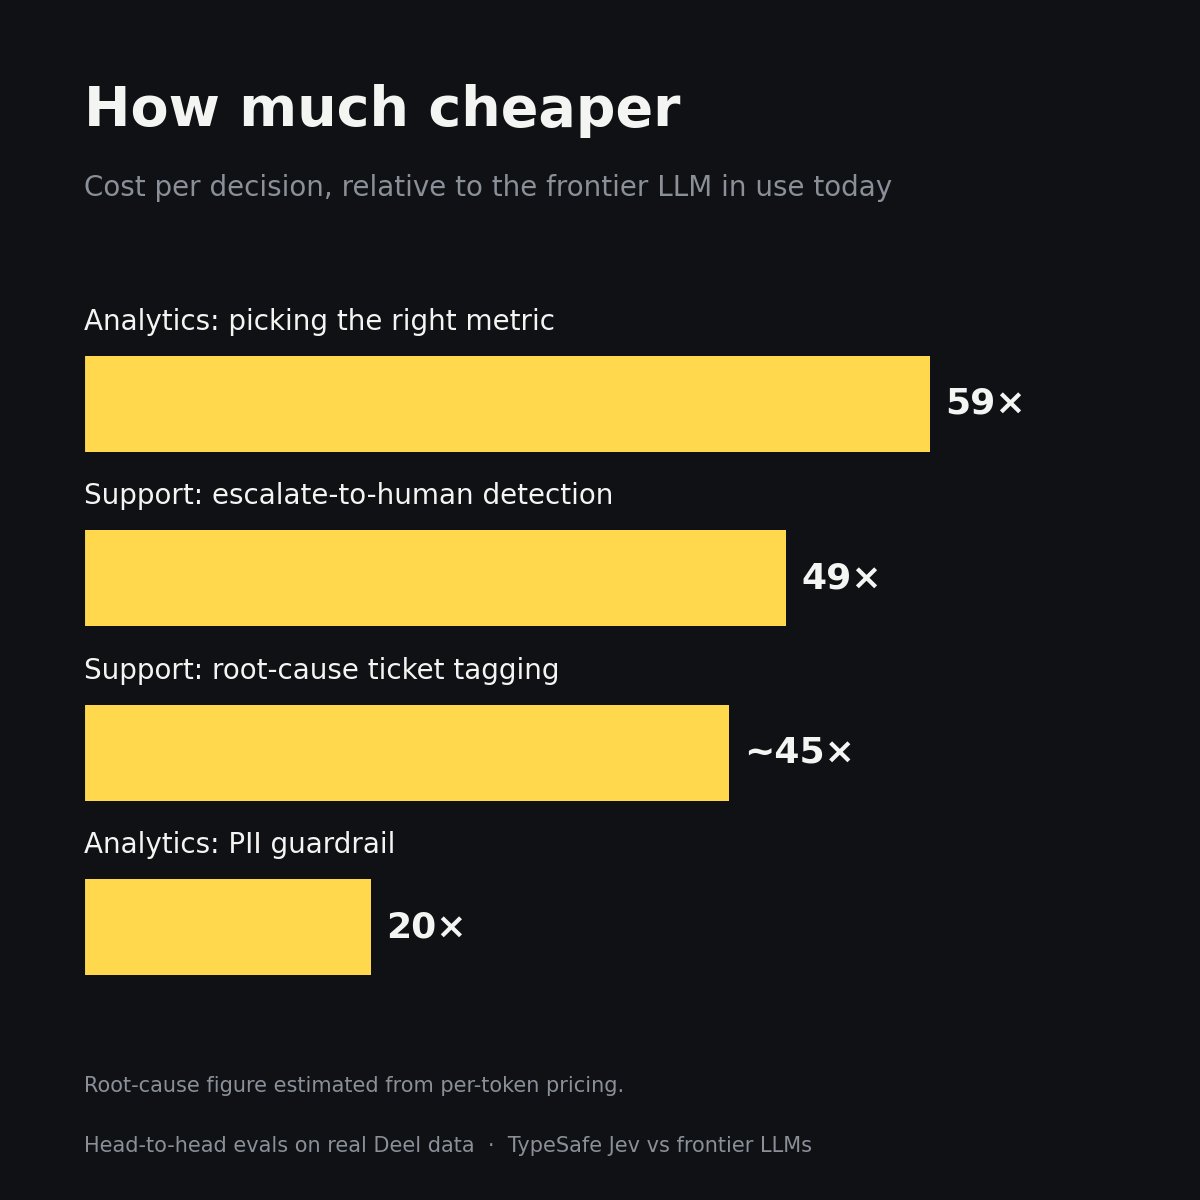
TypeSafe AI's Jev model outperforms frontier LLMs at lower cost in shadow-testing on live production traffic, achieving up to 4x speed and higher accuracy on tasks like repeat-question matching and expense categorization.
Highlights
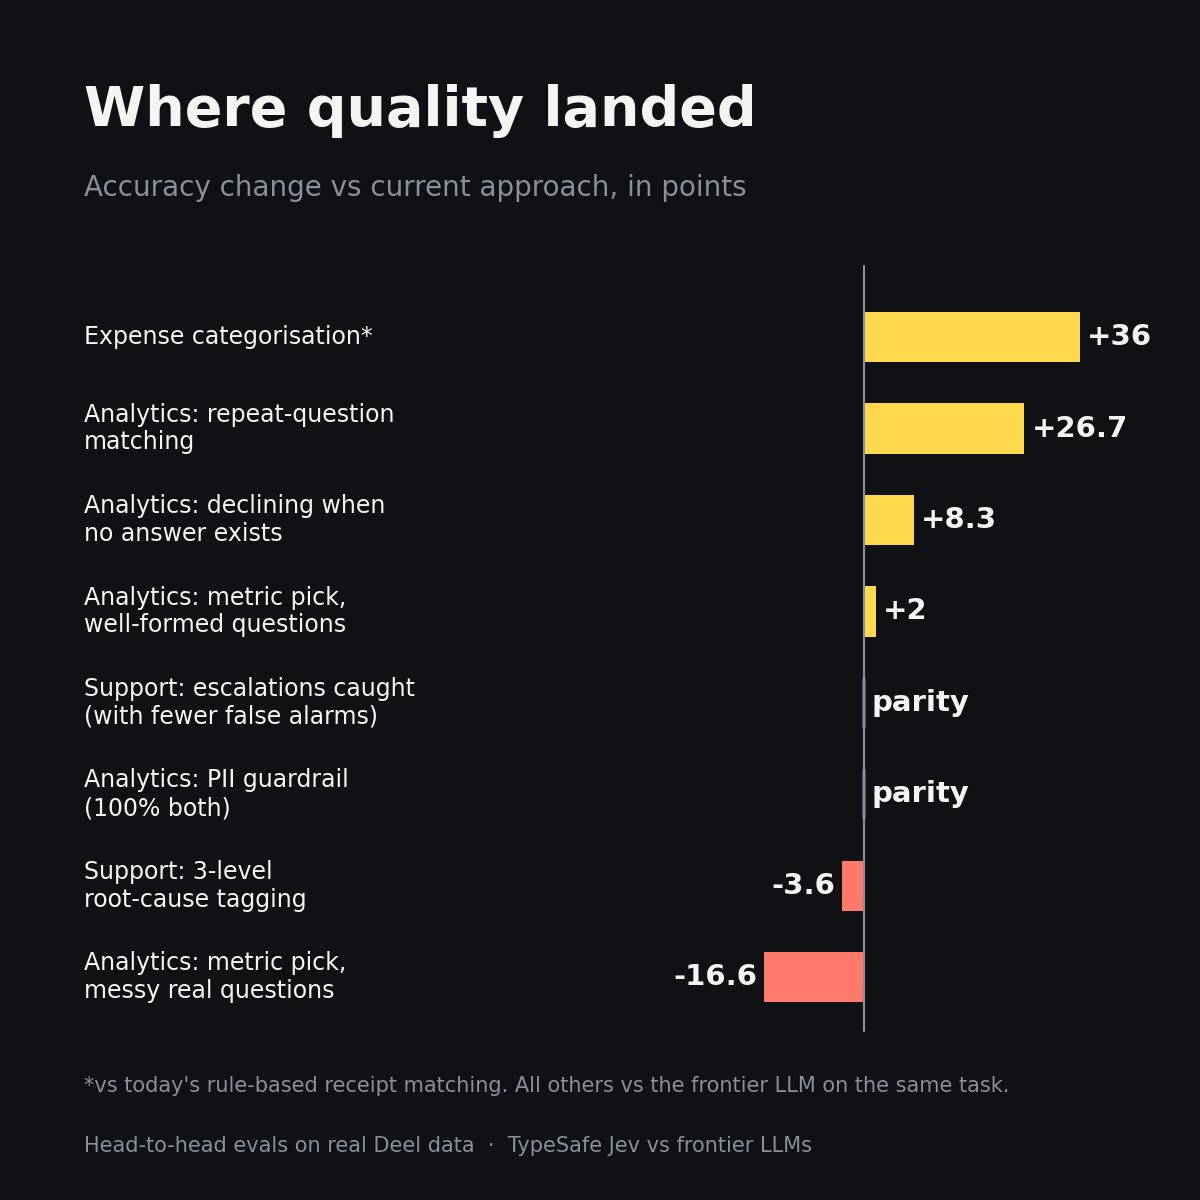
- Repeat-question matching accuracy improved from 70% to 97%.
- Expense categorization accuracy went from 50% to 86% (vs human reviewers).
- Escalation decisions caught the same issues with fewer false alarms.
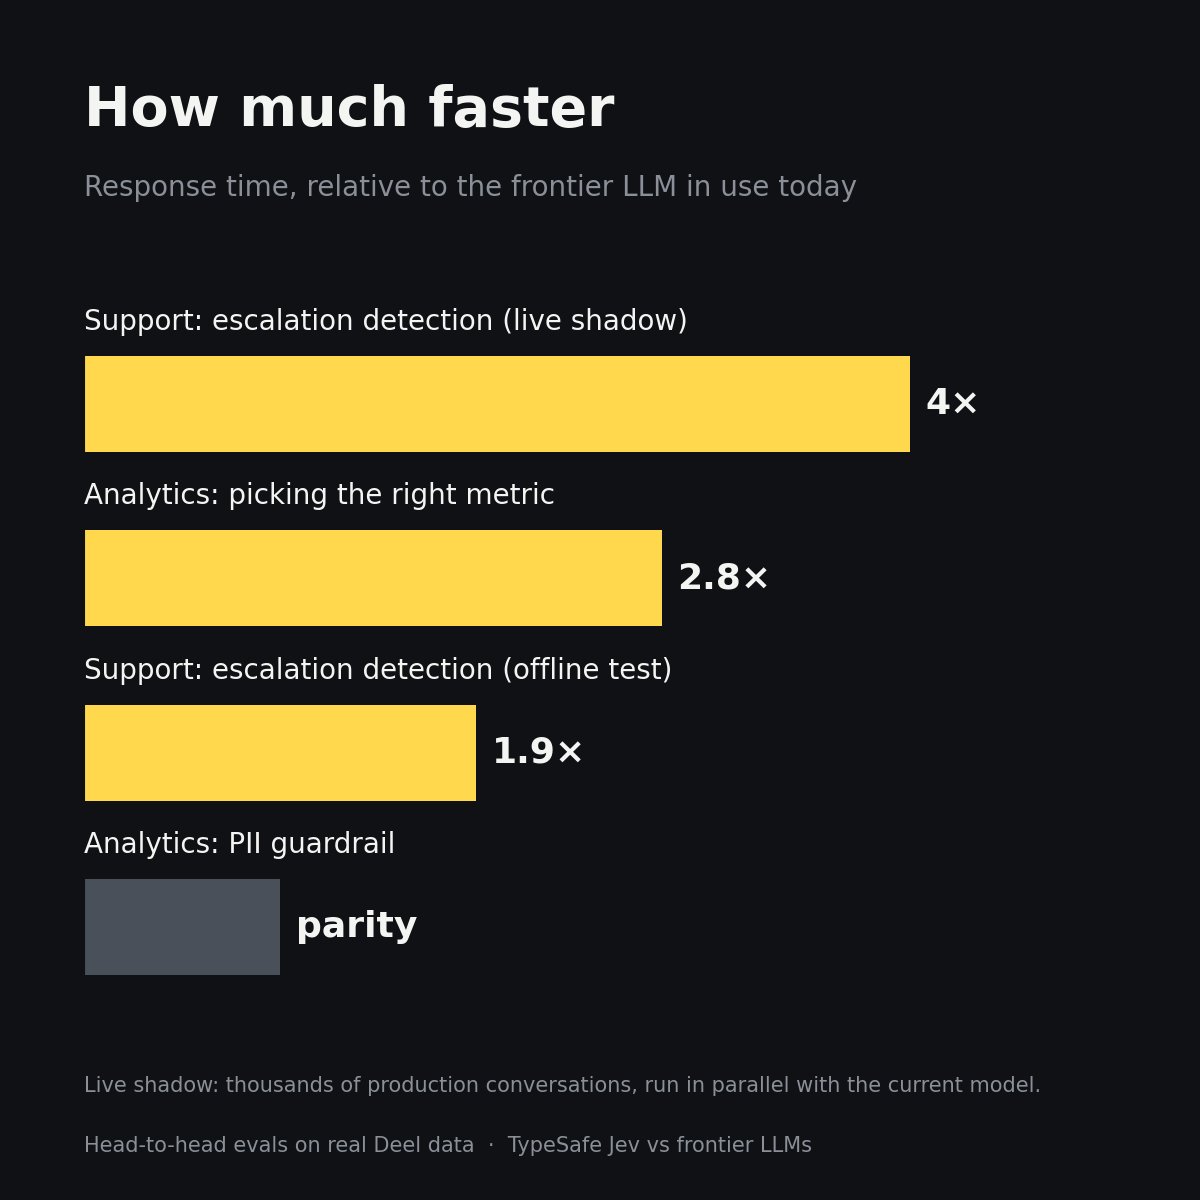
- Speed measured while shadowing live production traffic: up to 4× faster; offline tests: 2 to 3×.
- Use cases include selecting from known sets: matching analytics questions to approved answers, picking 1 of 36 metrics, blocking PII requests, deciding when a support chat needs a human, tagging tickets across a 3-level taxonomy, and sorting expenses into about 55 categories.