核心信息
8月份,仅13%的请求输入超过64k tokens,却贡献了77%的净缓存节省——因为长提示词包含更多可被缓存的重复上下文。
要点
- 长上下文请求占比虽小,却是缓存收益的主要来源。
- 节省并非因为长提示词本身更便宜,而是因为有更多重复上下文可供缓存利用。
- 对生产环境AI应用而言,优化重复上下文的缓存是降低成本的可行方向。
8月份,仅13%的请求输入超过64k tokens,却贡献了77%的净缓存节省——因为长提示词包含更多可被缓存的重复上下文。
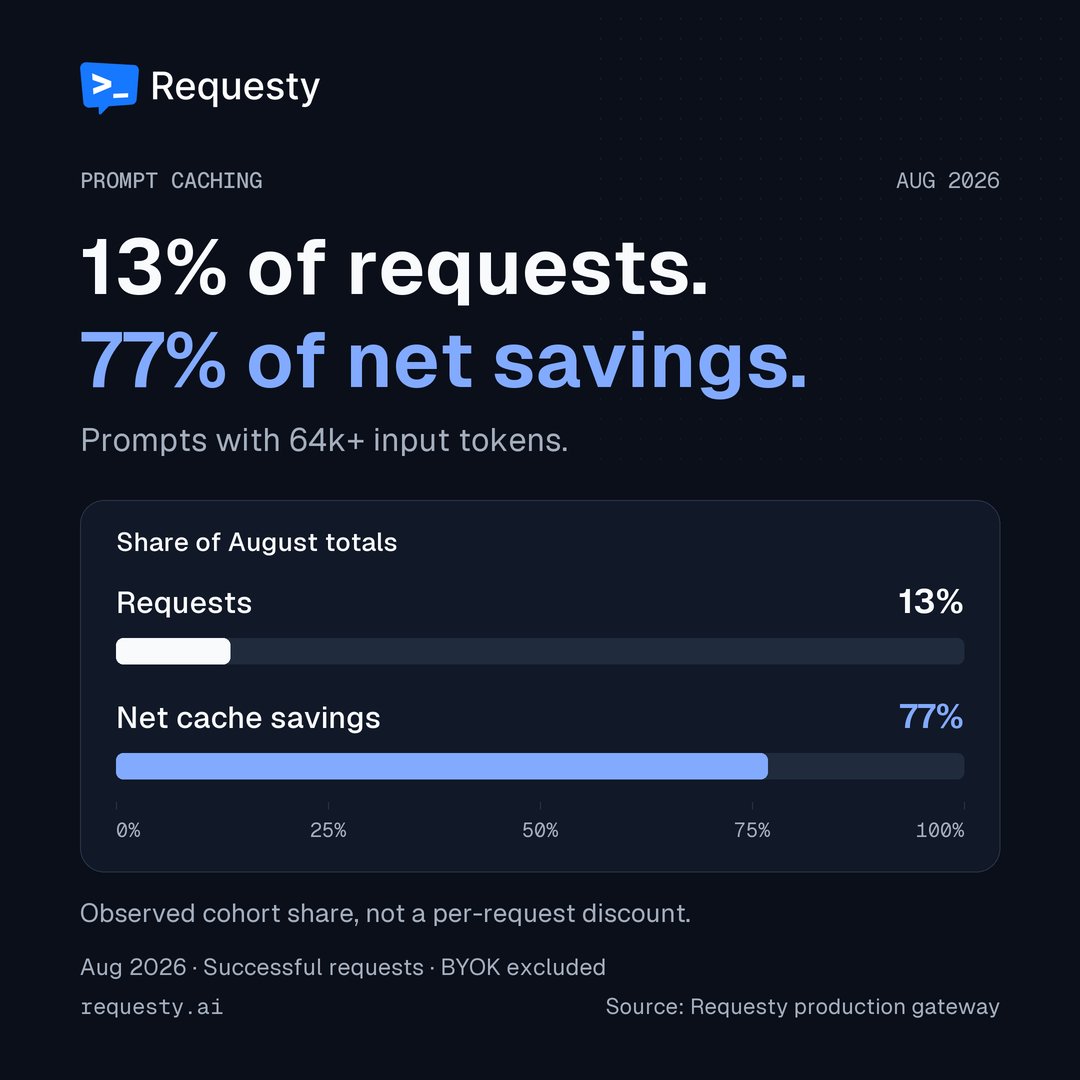
Prompts with 64k+ input tokens were only 13% of requests in August. They accounted for 77% of net cache savings. Not because longer prompts are inherently cheaper, but because there’s more repeated context for caching to work with. https://t.co/9ycSPiAELR
