
Key Info
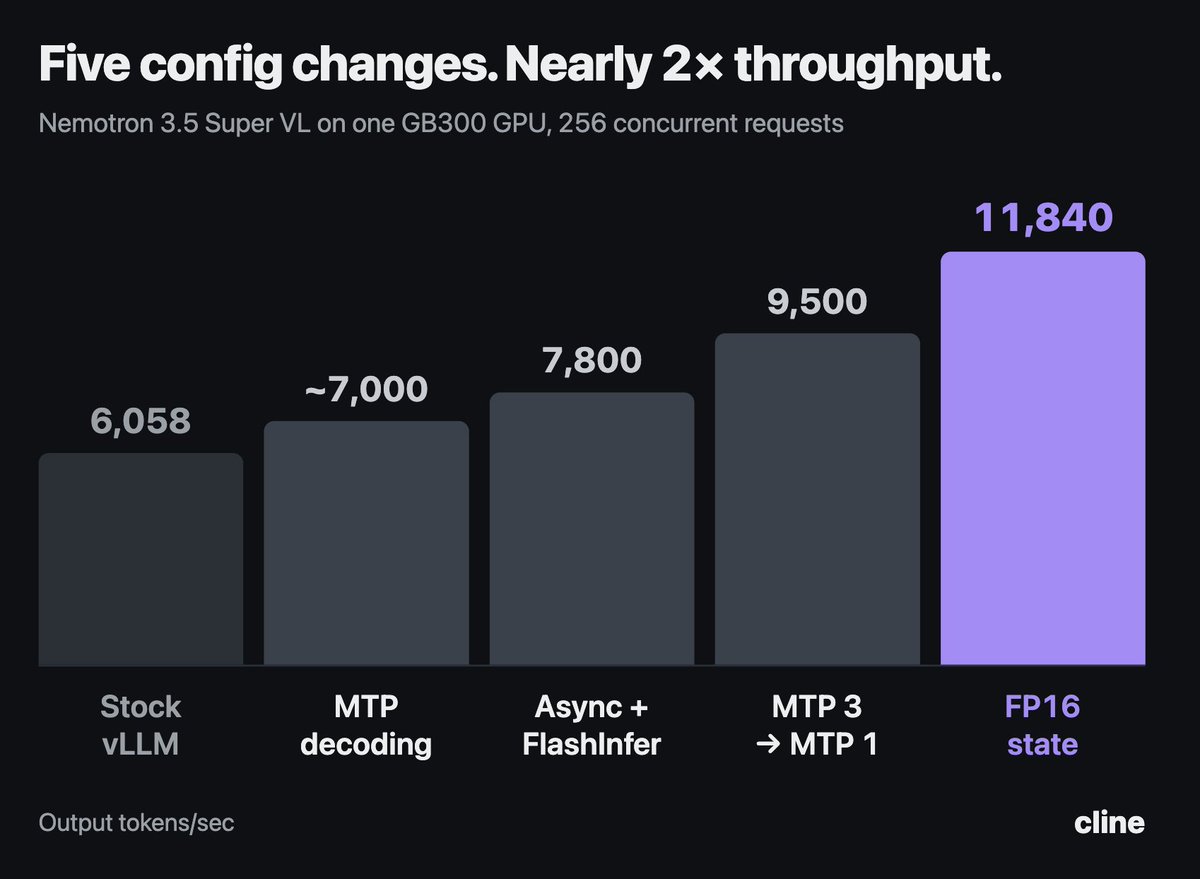
Cline nearly doubled inference throughput for Nemotron 3.5 Super VL on a single GB300 GPU, going from 6,058 to 11,840 tok/s through five configuration changes in vLLM.
Highlights
- Throughput rose from 6,058 to 11,840 tok/s on one GB300 GPU.
- The gains came from five vLLM configuration changes.
- Changes let the model draft tokens ahead, keep the GPU from sitting idle, and store model memory at half precision.
- Cline says it published further details on these techniques and on the future of local models and agentic inference.