Key Info
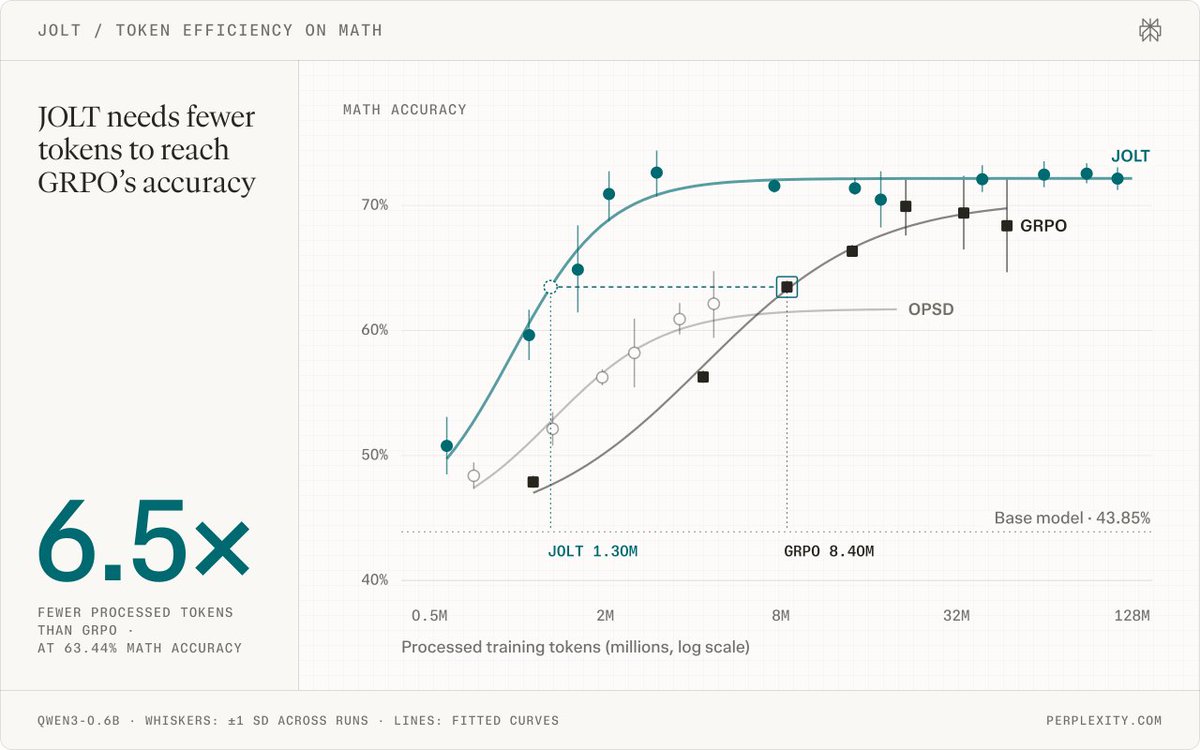
Perplexity researchers developed JOLT, a post-training method in which one model serves as both teacher and student, with the teacher trained to produce feedback the student can actually use. On MATH it matched GRPO's accuracy using 6.5x fewer training tokens.
Highlights
- Standard self-distillation trains only the student, letting the teacher exploit shortcuts the student cannot access; JOLT also trains the teacher on outcome rewards from its own attempts.
- A penalty is applied when the teacher's predictions diverge from the student's, keeping the feedback usable.
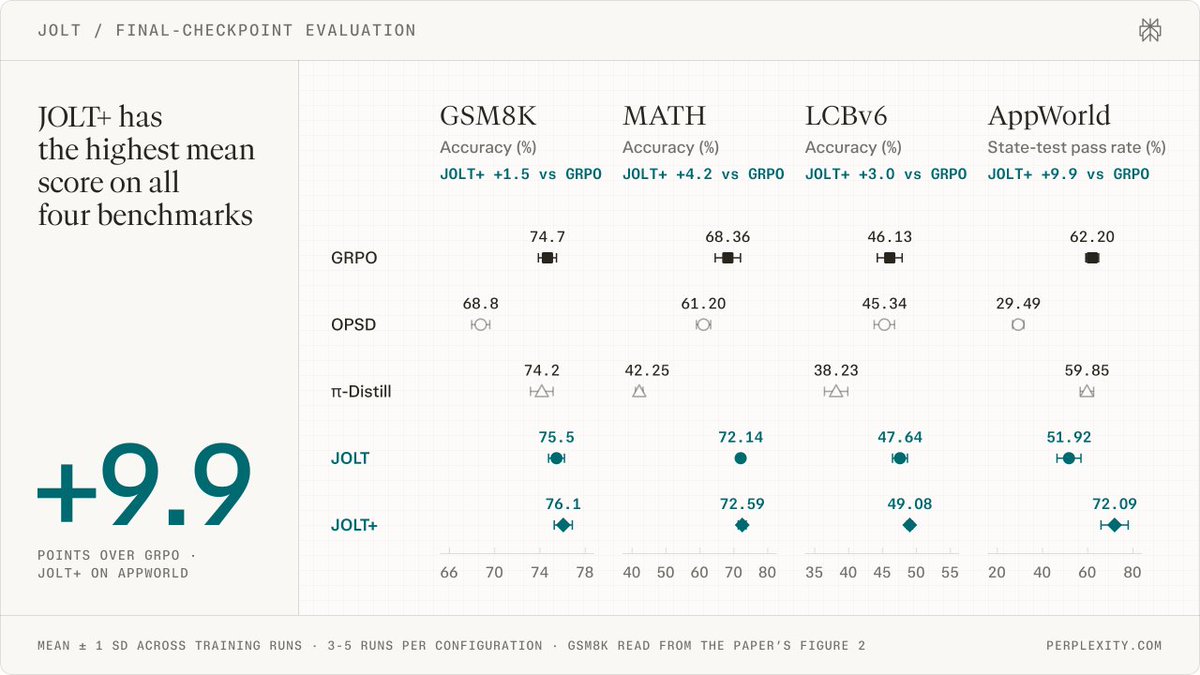
- JOLT+ beat GRPO on all five benchmarks spanning math, coding, tool use, and terminal tasks.
- It gained 9.9 points over GRPO on AppWorld.