
Key Info
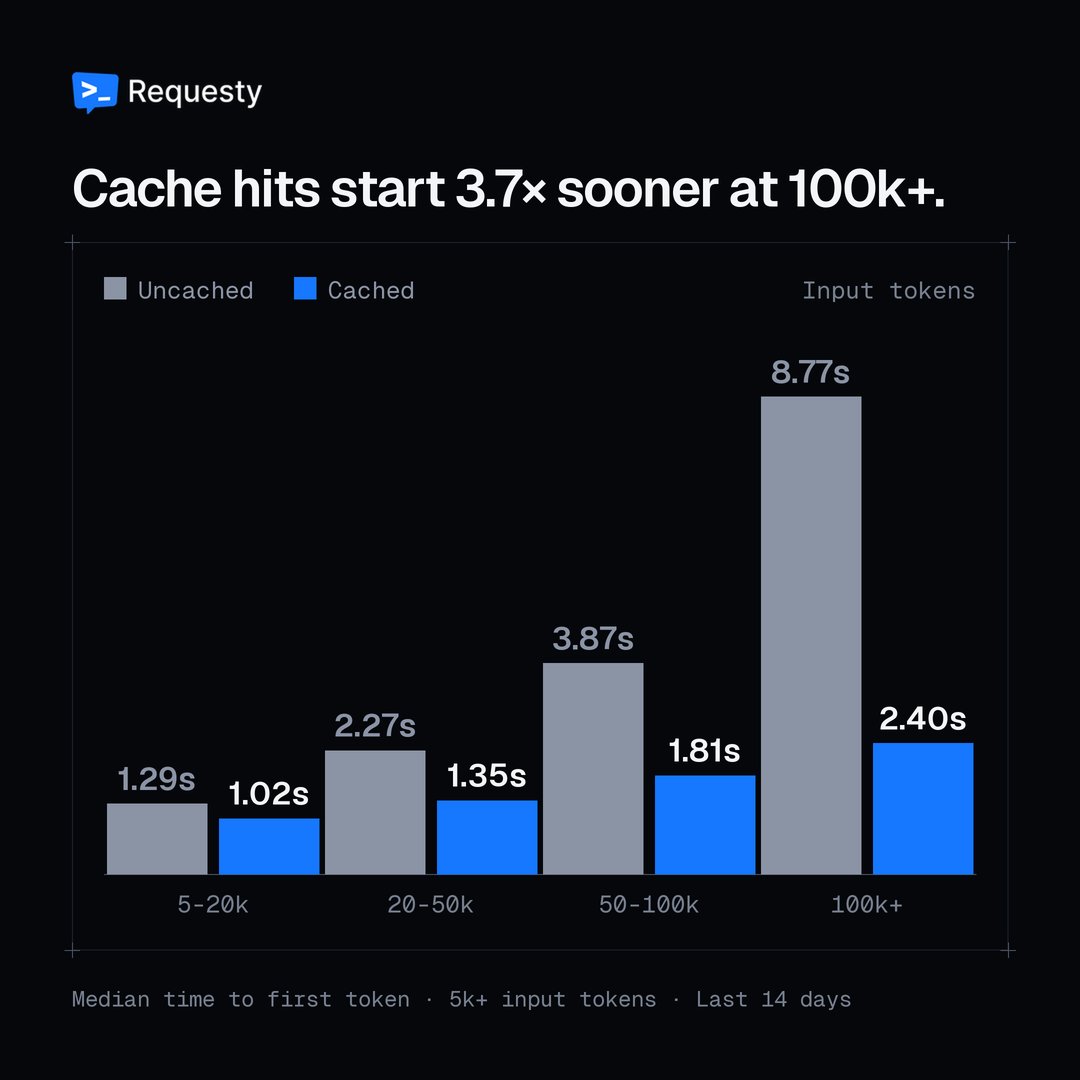
Requesty shared internal data showing that on requests over 100k tokens, serving the prompt from cache reduced median time to first token from 8.8s to 2.4s.
Highlights
- Measured on 100k+ token requests routed through Requesty
- Median time to first token dropped from 8.8s to 2.4s with cache hits
- The company notes cost savings remain important, but latency is what end users actually feel
- Suggests prompt caching is a latency optimization, not just a billing one