
Key Info
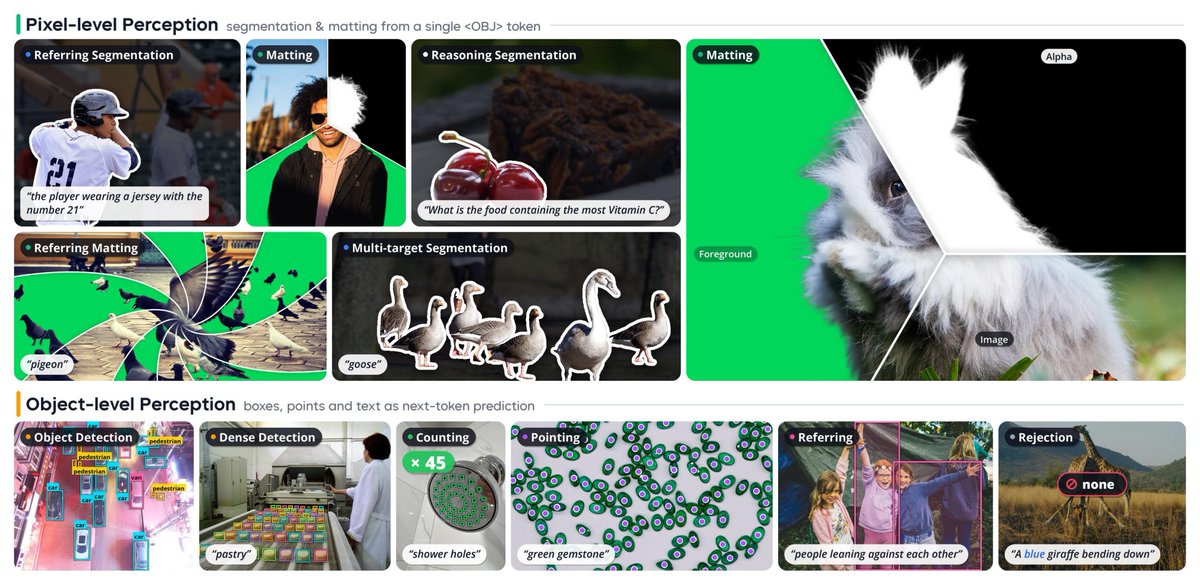
Tencent has open-sourced WeVisOne-VL, a 4B vision-language grounding model that returns None rather than a bounding box when the requested object is not present in the image.
Highlights
- On the team's WeRef benchmark it rejects 96.4% of queries for absent objects; on the public Ref-ZOM benchmark it rejects 86.0%.
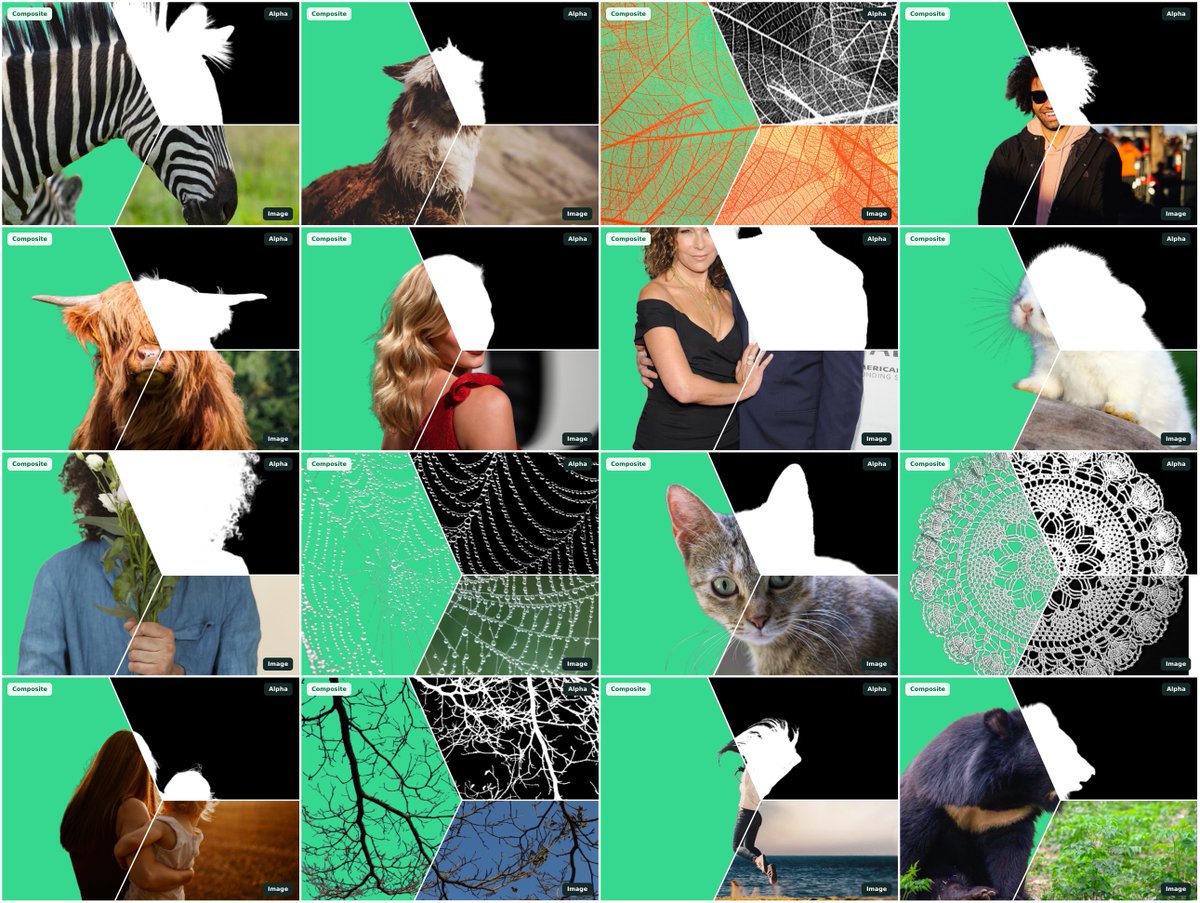
- A single set of weights handles five tasks that previously required separate models: detection, counting, OCR, masks and alpha mattes.
- Alpha mattes come from a 9.6M-parameter decoder and provide soft per-pixel opacity, preserving hair, fur and semi-transparent edges better than binary masks.
- The pipeline does not use SAM and currently supports images only; scores are rerunnable with the repo's evaluation code.